

Grounded Generative Vision – Language Models for Radiology
SECTOR:
Healthcare and Life Sciences
COUNTRY:
Turkey
Short description of the innovation study
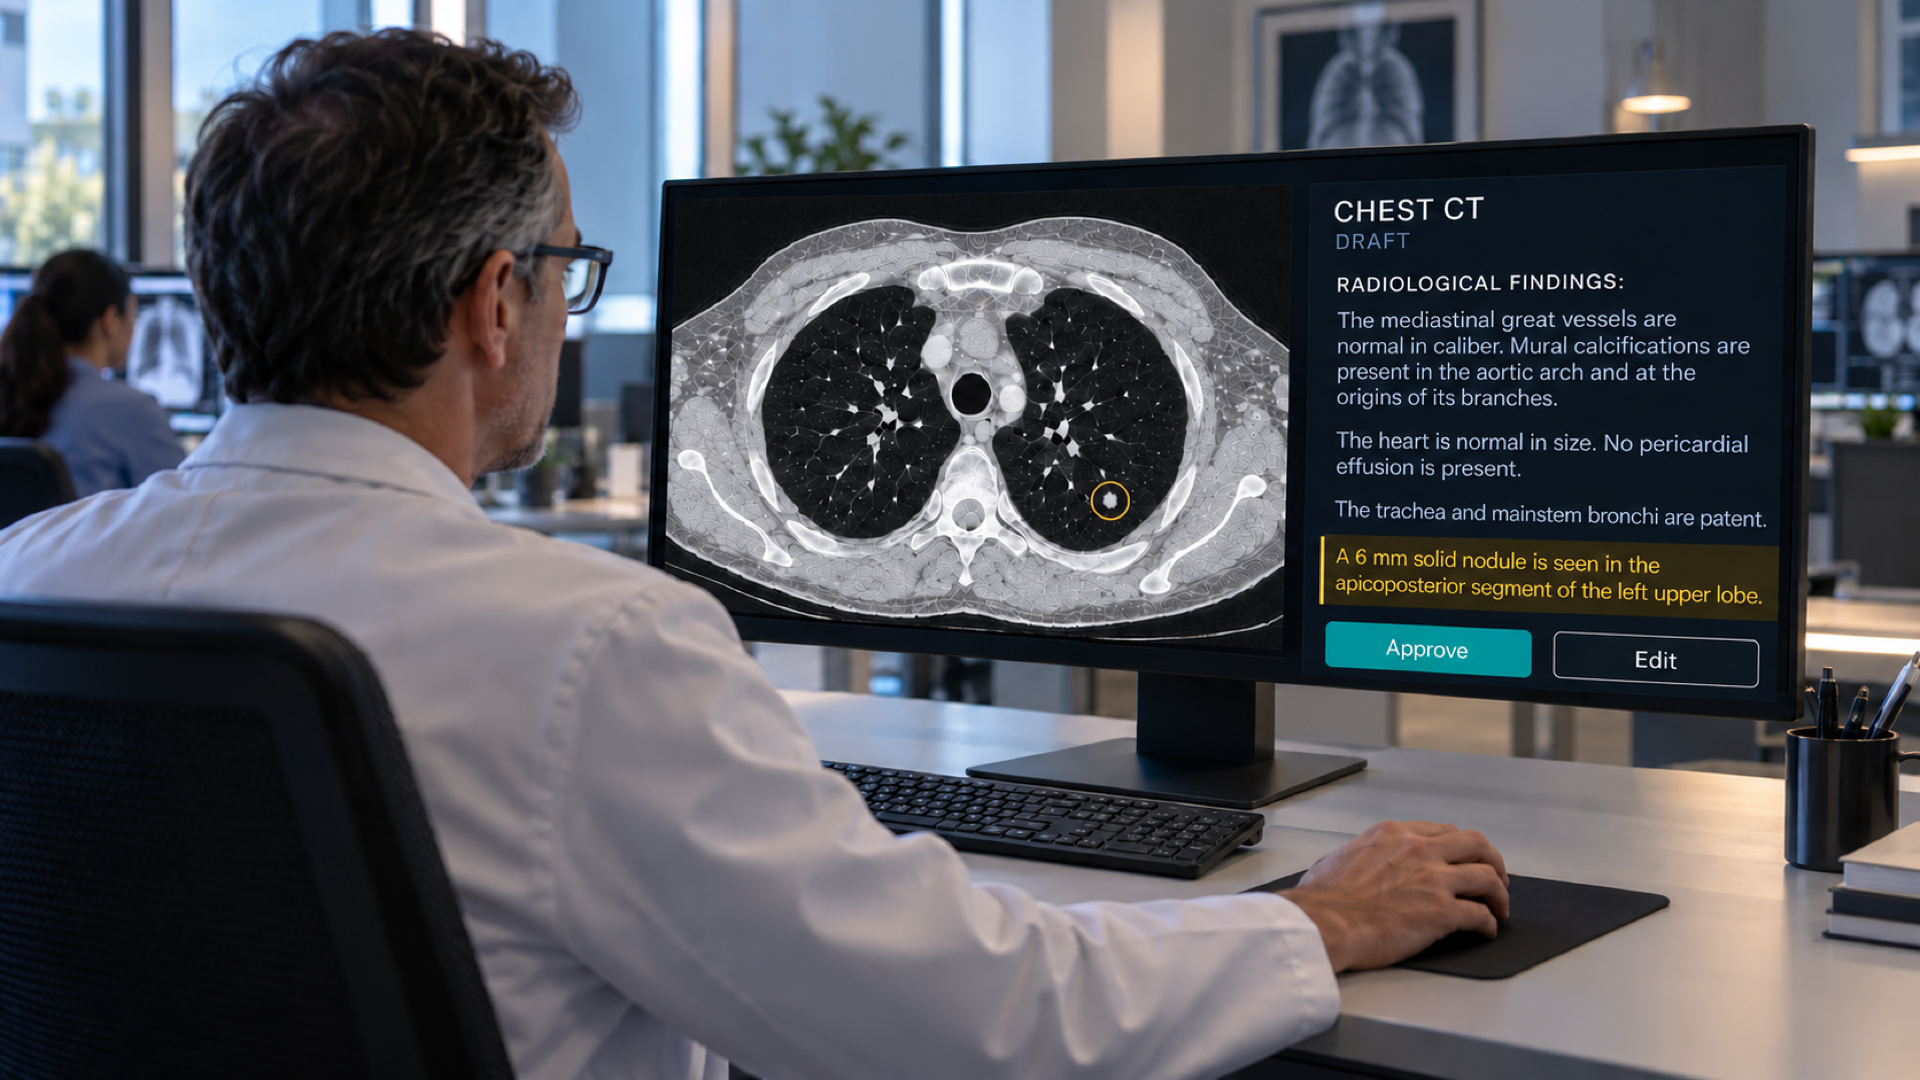
GRAVITY-RAD develops a grounded vision–language model for thorax CT reporting, linking descriptions of findings to the image regions they describe. Image-to-text models can hallucinate findings and miss small lesions. The study follows a "detect first, then describe" approach: CT detectors locate findings and a fine-tuned language model generates reports linked to image evidence. The study aims to reduce thorax CT reporting time by 25–40% and clinically relevant hallucinations and false positives by more than 50% compared with direct image-to-text baselines, while keeping the radiologist in control.
Organisations involved:
Main SME: Logethra Teknoloji A.Ş.
Technology expert: Dokuz Eylül University